

Imagine the following scenario. An AI agent is helping to prepare a regulatory report. It notices that a number moved enough to make a paragraph of descriptive commentary completely stale.
Now, of course, it can find the affected passages, prepare a revised explanation, compare figures to a previous version. It can identify the reviewer in charge and even draft the email asking for sign-off of the new figures.
In a more ambitious implementation, it could also update a working draft, change the workflow status, and actually send that message.
And that’s the exact moment where the question gets tricky because it’s no longer “Can the agent do this?” Of course, clearly it can do this. The question becomes, “Which of these actions is it allowed to take without a human deciding?”
AI agents don’t behave like mature adults in the workplace. They’re more like very, very capable kids, and so we need to give them exact guardrails to act.
An AI agent is not like a junior colleague (junior but adult) who would make the right judgment call based on their own values and those of the company. An agent doesn’t have values; will do exactly what you ask from it without scrutiny — and with possibly unintended consequences.
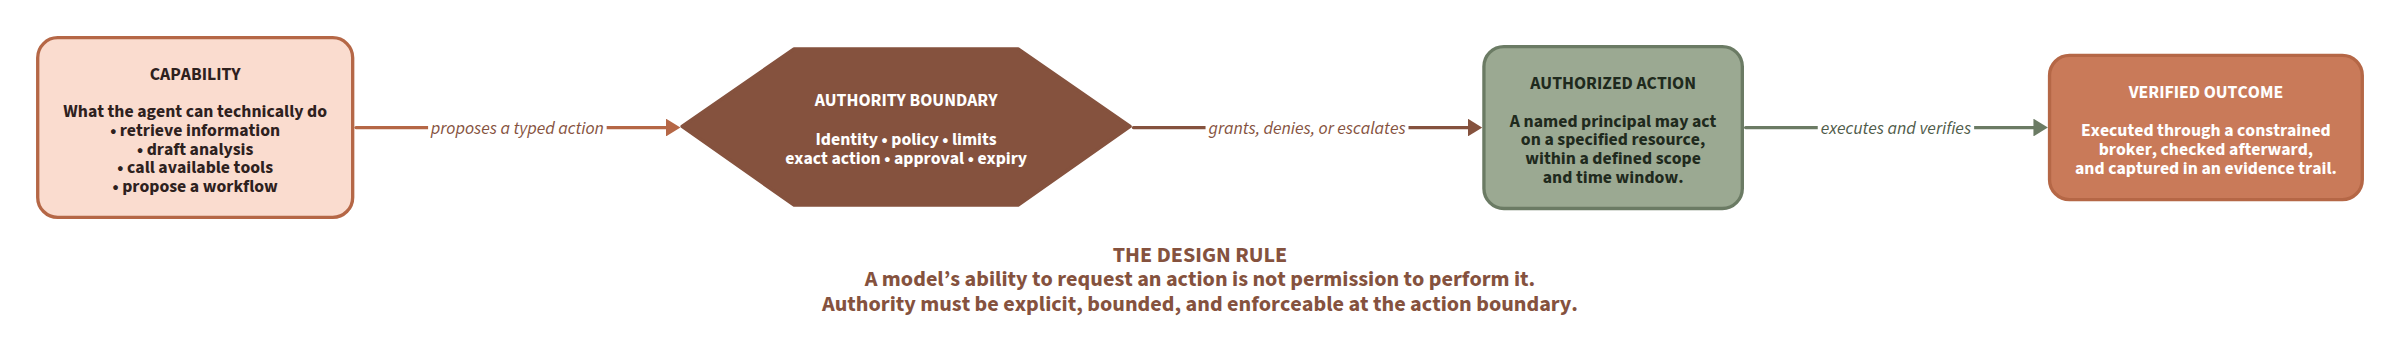
In our enthusiasm about agents, we often blur capability and authority. Capability is what the system can technically do. Authority is what the organization has actually allowed it to do. For example, acting for a named person or team against a specific resource with a defined scope, value limit, environment, and a time window.
An agent may be capable of sending an email, but it might not be authorized to send it. It might be capable of preparing a payment, but not authorized to commit it.
The fact that the system can reach a button doesn’t mean it’s been given the right to press it. AI Wide Open recently published a piece on agents operating entire computers, and made this phenomenon quite tangible.
The machine is no longer just calling a small menu of APIs; it can increasingly operate inside the software environments where people work, communicate, shop and manage information.
And that means that the number of available actions is increasing faster in any case than the clarity around its permissions.
A system that can improvise across software is of course more powerful, but also more dangerous because it encounters many more situations that require judgment about intent, acceptable trade-offs and consequences.
So agents are becoming more and more technically impressive — but how do we rein these capabilities in so that we don’t see inevitable snafus happening?
The mistake: treating tool access as delegated judgment
Now, most early agent designs still make a very old security mistake. They hand a new kind of actor a broad credential and then just ask it to behave. The prompt says, “Only do sensible things.” The system actually has a service account, a browser session, and a set of powerful tools, and then we call the arrangement autonomous.
But a prompt is not a permission system, it’s a guidance. For a probabilistic model, the UK National Cybersecurity Centre makes the same point in a bit plainer language. Define what the agent may do, may not do, and when it must seek approval, but do not rely on prompting alone. Combine it with technical and operational controls.
A human with access to a financial system still operates within a web of role expectations, legal duties, experience, and social consequences. An agent has none of this. It just has instructions, tool descriptions, data and context, and the technical permissions we put around it.
That doesn’t make agents useless, but the surrounding architecture carries more of the responsibility than it did when it was just humans and deterministic software.
That’s the same lesson we learned in reporting. Fluent output isn’t evidence. A beautifully phrased sentence doesn’t become defensible because the language model was confident. Likewise, a technically successful tool call doesn’t become appropriate just because the agent had access.
In either case, the decision needs an accountable fact base, a clear boundary, a named owner, and a recoverable audit trail. This ties back to our previous article, Would you let AI write your regulatory reports? Facts flow into text, text doesn’t get invent any facts. The parallel is: policy flows into execution, the model doesn’t get to invent permission.
A practical authority map for agents
Just like a gifted child may still touch hot pots and hurt itself, or even others, so an AI agent can get seriously burned if they are not careful and don’t have the right guardrails in place.
So for every action that an agent may take, five things need to be specified up front:
Who is acting? Is this a named human using an assistant, an agent acting for that human, or a system agent acting on its own? Modern enterprise platforms are beginning to formalize this, distinguishing user-delegated authority from an agent’s own authority, and supporting audit trails that show both user and agent identities when an agent acts for a person.
What exact action is being authorized? “Help with the report” is an objective but not an authorization. “Update draft section 4.2 in the working document” is a bounded action. “Submit the final filing” is a very different class of actions. The authorization should be tied to an action, target, and normalized parameters, not to some vague promise that the agent will pursue a helpful goal.
Which resources and environments? An agent may read the reconciled reporting data for one legal entity, but not every historical file in the company. It may write to a draft workplace space, but not in the signed final document. It may test an integration in a sandbox, but not deploy the same change to production. Access should be granular enough to match the action being requested, but not inherited wholesale from the person who happened to start the conversation.
Within which limits and for how long? Authority should expire. It should have a maximum volume, value, number of recipients, and a time window where those matter. An agent that can prepare a customer email draft for review shouldn’t quietly inherit a standing right to send an unlimited number of emails tomorrow. OAuth’s central idea is already familiar, which is that a third-party receives unlimited access on behalf of a resource owner or on its own behalf through an authorization layer, not the owner’s entire password and life story. The same principle can be applied to agents.
What happens when the agent is uncertain or their action is consequential? The answer can’t always be “continue and explain later.” The agent needs a proper escalation path (such as: “Stop and surface the blocker.” Or, “Show the proposed action in a human-readable form and wait for a decision from a human.”) For high-impact or irreversible actions, approval should be tied to the exact action, the target, parameters, timestamp, and expiry, not just the broad task. If the recipient, amount, document, version, or policy changes after approval, the approval should no longer be valid.
When these five points are thought through in advance and made clear not just in some word document but in the actual code, then companies are in a much better footing to deploy agents reliably.
Where humans come in
This may sound like humans are being automated away almost completely, except for a little bit of red tape. That’s not the case. Just like a responsible parent is not automated away by a gifted child.
The answer isn’t to place a person in front of every click that an agent makes, of course. That just turns the agent into a very expensive autocomplete tool. It’s like a helicopter parent, really, for the human behind it. And nobody likes to be a helicopter parent.
The answer is also not to place a person at the end of a really long workflow and then asking it to rub a stamp after the consequences have already happened. That’s like giving a highly gifted but rather young child a car to drive and letting the parents figure out the details after the inevitable crash has happened.
The really useful question is: At which decision does human accountability actually matter? Here are a few action items that may help think this through:
Observe: reading a bounded data source, retrieving an approved definition or flagging an inconsistency. This can often proceed automatically.
Draft: preparing commentary, a recommendation or work plan in a staging space. The agent may proceed, but the output remains clearly a draft.
Reversible internal action: updating a non-final workflow or state or preparing a ticket. These may be automated if the action is limited, attributable and easy to correct.
Consequential action: sending an external communication, altering a production system, disclosing sensitive data, approving a payment or changing access rights. Here the system should clearly require an exact action review and independent enforcement.
Critical or irreversible actions: submitting a regulatory filing, making a high-value transfer, deleting a large dataset, or altering a foundational access policy. At this point, the right design may be that the agent prepares the evidence and the human performs their final operation through a defined runbook.
Depending on the company, there may be more or less of these action items, or other categories entirely. At Wangari, this categorization is the reason why we don’t give the language model a calculator, and a signature stamp for regulatory reporting documents. The calculation is deterministic in our world, and therefore enforced in code. The facts are approved by humans. The agent can just draft and point out exceptions. Humans remain as the gates where responsibility has to remain visible.
And for us, that’s not an anti-automation compromise. It’s what makes ambitious automation defendable. NIST’s GenAI profile similarly recommends post-deployment monitoring that covers override, decommissioning, incidence response recovery and change management, and not just model output quality.
Approval is not (just) a button
Now, many human-in-the-loop designs effectively ask a person to click the “approve” button after presenting a broad natural language summary. That may create comfort, but it’s not really a meaningful control.
The human may have approved a proposal to send the update where the agent has changed the recipient list, attached the wrong file, or included a sensitive data field. A meaningful approval therefore needs to show the agent’s proposed action in plain language, but also the exact target (the recipient, report version, system or account), the consequential parameters (account amount, volume, data class, deployment environment), and anything that can’t be reversed.
The source and rationale where action rests on data, the named approval, decision time and expiry date, and the approval crucially must be invalidated if the underlying action changes. The point here is not to introduce red tape or manufacture friction, but it’s to put friction at the very moment at which the organization is actually delegating responsibility.
Good automation removes the search, the formatting, the copy-paste, and the needless handoff. It doesn’t remove the moment at which somebody needs to stand behind a consequential act.
A decision record, not a diary
When an agent completes a workflow, a final chat message like done isn’t enough. Neither is a detailed recording of every token or every mouse movement needed.
But for a consequential action, an organization should be able to reconstruct the important chain of decisions. The minimum scope then becomes:
Request. What was the task and who initiated it?
Proposal. What action did the agent want to take based on which evidence?
Policy decision. Was it allowed, denied, or escalated and under which policy version?
Approval. Who approved the exact action if approval was necessary?
Execution. Which constrained component actually performed the action?
Verification. What evidence says the intended result occurred or that the state is still unknown?
A conversation trace tells you what the system said. A decision record tells you what the system was allowed to do, what it did, and who owns the result.
NIST’s Zero Trust architecture separates the decision to grant or deny access from the component that enforces access. It also emphasizes a granular individual resource request rather than inherited implicit trust.
This is not an AI standard, but it’s the kind of mature access control thinking that agent builders really should borrow.
The best agents know when not to proceed
The best reporting agent doesn’t panic when it finds a variance in the numbers. It just tells the team what changed, which statements may now be affected, which evidence supports the proposed explanation, and who needs to decide.
It doesn’t pretend that the ability to edit a sentence gives it the authority to rewrite a signed narrative. Just like when your gifted child comes home from school saying that an important test is coming up at school. The mature child will also ask you as a parent if there are any resources that it can use to prepare for that test, rather than eagerly starting to try to prepare it all by itself, and floundering in the process.
We spent the last few years measuring AI progress by what models can do unaided, and that’s understandable given how fast the technical capabilities are growing. But for enterprise agents, this is incomplete. The practical measure of autonomy isn’t how many steps happened without a human, it’s how much responsibility can safely be delegated without losing clarity over authority, verification, and accountability.
Before giving an agent access to a real workflow, here’s what you should ask:
What can it see?
What can it change, send or commit?
Which actions are only proposals?
Which actions require fresh approval?
What is the smallest permission it needs?
Can we reconstruct the consequential decisions afterwards?
Can we halt it and complete the work safely if something goes wrong?
If these questions don’t have clear answers, the organization has not given the agent autonomy, it’s given it ambiguity. Capability creates the opportunity. Authority design determines whether the opportunity is safe enough to use.
Meanwhile, at Wangari
We’ve been busy at work making our flagship product, etio, even better. We’ve improved not just the frontend interface but also how AI interacts with facts, and we’ve managed to attack AI output — with very promising results.
We’re proud to be featured on ShipAI! It’s a new format by Towards Data Science, dedicated to showcasing AI products in a digestible and fun way.
Reads of the Week
AI Wide Open has a few very astute observations to share on the state of human control in the age of AI. The key line: AI is moving from using tools to operating environments. The hard problem is no longer whether an AI can operate software, but what it is allowed to see, change, send, buy, or decide on somebody else’s behalf. The core of the problem is the “agent visibility gap,” i.e., we currently don’t know what agents are doing and why — and that’s a gap worth closing. The real currency in AI is not how much it can produce (very much), but how much it can be trusted with real-world decisions.
Sameer Bhanushali has slightly different take on AI governance. Capability becomes a governance problem when an agent can authenticate, invoke tools, and act against enterprise systems. The practical answer is not more prompting, but creating distinct agent identities, scoped and expiring authority, and an auditable delegation chain. It’s informative as a clear bridge from agent capabilities (where most companies are at) to agent authorizations, limits, and controls.
Amy Swaner has a very interesting piece on agentic AI in law (not on your in-laws — sorry, couldn’t suppress the pun). It’s interesting how many junior lawyers seemed to have jumped on the hype without the same prudence they’d use on human assistants. The problem compounds, because AI agents have zero fiduciary duty! Interestingly, the guardrails for using agentic systems (i.e., the equivalent of a junior legal associate) and agent-ish systems (e.g., like a paralegal with a detailed checklist) turn out to be practically the same as for human legal staff. Which means that legal folks might simply need more discipline around AI.
Really liked how you framed the shift from capability to authority here.
An agent being technically able to do something tells us very little about whether it should be allowed to do it. As agents move from calling tools to operating inside real environments, that distinction becomes much harder to ignore.
The visibility gap is only part of it. We also need to know where the authority actually ends.